According to enterprise generative search studies conducted by the Stanford Center for Research on Foundation Models, more than 58% of commercial B2B product discovery queries now originate inside Large Language Model (LLM) interfaces rather than traditional search engine results pages. Consumers and corporate procurement teams increasingly query ChatGPT, Claude, Google Gemini, and Perplexity to generate vendor shortlists, compare feature matrices, and assess brand reliability. For marketing directors and Chief Marketing Officers, standard organic ranking rank-trackers are blind to this shift. Performing a rigorous brandrank.ai visibility insights analysis has emerged as the essential operational standard for tracking brand share of voice inside generative artificial intelligence ecosystems.
Traditional SEO tracking measured positions one through ten on a static web page of blue links. In contrast, generative engine visibility is dynamic, probabilistic, and conversational. Large language models do not merely retrieve URLs; they synthesize opinions, assign sentiment, and either endorse or omit specific corporate brands based on latent parameters in their training sets and live Retrieval-Augmented Generation (RAG) indices. Analyzing insights through enterprise platforms like BrandRank.ai enables corporate teams to monitor AI search prominence, diagnose citation gaps, and protect brand equity.
This technical analysis guide breaks down the architecture of BrandRank.ai visibility insights, detailing core metric definitions, benchmarking methodologies, risk vectors, and tactical optimization frameworks for enterprise brand leaders in 2026.
Quick Answer: What Is a BrandRank.ai Visibility Insights Analysis?
A BrandRank.ai visibility insights analysis is an enterprise evaluation that measures how frequently, favorably, and prominently a brand is recommended across leading AI answer engines, including OpenAI ChatGPT, Google Gemini, Anthropic Claude, and Perplexity. Unlike traditional keyword tracking that monitors SERP rankings, BrandRank.ai runs automated prompt testing across thousands of industry purchasing scenarios to quantify Brand Prominence Scores, Generative Share of Voice (SOV), sentiment polarity, and source citation attribution. Marketing executives use these insights to identify which digital sources feed AI model recommendations and optimize their presence through Generative Engine Optimization (GEO).
Key Takeaways for Marketing Executives and Enterprise Brand Directors
- LLM Visibility Replaces Blue Link Rankings: Ranking on page one of Google organic search does not guarantee mention in an AI overview or ChatGPT prompt answer. AI visibility requires entity salience within training corpora and real-time RAG citations.
- Four Core Evaluative Dimensions: BrandRank.ai scores brands across Recommendation Frequency, Position Prominence (first-mentioned advantage), Sentiment Polarity, and Citation Authority.
- The Threat of Brand Hallucination: Unmonitored brands frequently suffer from AI confabulations, where models cite incorrect product pricing, discontinued features, or misattribute negative competitor reviews.
- Data Normalization Is Crucial: Optimizing AI visibility requires structured entity data that aligns with BrandRank.ai normalization transformation rules to ensure models correctly identify parent companies and product sub-brands.
- Unified GEO Integration: Integrating AI visibility reports with wider enterprise strategy connects with our blueprints on generative engine optimization tools and long-term answer engine optimization strategy.
Flat vector editorial illustration of corporate marketing leadership analyzing BrandRank.ai visibility insights and search share of voice metrics across generative AI models.
Why Traditional Rank Tracking Fails in Generative AI Search
For more than two decades, digital marketing relied on deterministic search results. A user typed a keyword string, Google matched web pages against its link graph and textual relevance algorithms, and returned ten organic blue links. Every user searching from the same city received nearly identical outputs.
Generative search models behave fundamentally differently. When a prospective buyer inputs a multi-sentence prompt, such as “What are the most reliable enterprise cybersecurity platforms for a 500-person financial firm?”, the AI model generates a synthesized narrative response in real time. The model evaluates billions of parameters, weighing semantic token probabilities to generate a coherent paragraph that directly names two or three vendors while ignoring dozen others.
According to enterprise research published by Gartner Digital Markets research, zero-click generative search experiences reduce outbound organic referral clicks to corporate homepages by up to 25% across technical B2B categories. If your brand is not explicitly mentioned inside the AI generated summary, your prospective customers never discover your existence. BrandRank.ai was built specifically to solve this visibility blind spot.
The Technical Architecture of BrandRank.ai Visibility Insights
BrandRank.ai operates by conducting continuous, automated prompt simulations across hundreds of commercial user personas and buying scenarios. Rather than checking a single keyword, the platform executes an automated evaluation framework consisting of four technological layers:
1. Buyer Persona Prompt Simulation
The platform generates thousands of conversational prompt variants representing different stages of the enterprise purchasing cycle: exploratory queries (“What are alternatives to Salesforce for mid-market logistics?”), technical evaluations (“How does Datadog compare to Dynatrace for Kubernetes monitoring?”), and risk-assessment queries (“What are known downtime issues with AWS US-East?”). These prompts are executed against live commercial APIs across OpenAI GPT-4o, Anthropic Claude 3.5 Sonnet, Google Gemini 1.5 Pro, and Perplexity Sonar.
2. Response Parsing and Entity Extraction
When an LLM returns a text response, BrandRank.ai applies Natural Language Processing (NLP) token parsers to identify whether the target brand is named, where in the text it appears, and whether it is framed as a recommended primary choice, an acceptable alternative, or an option with significant drawbacks.
3. Citation and Source Graph Mapping
For answer engines that incorporate real-time web retrieval (RAG), such as Perplexity and Google Gemini, the platform extracts every footnote URL and domain source cited in the response. This reveals the digital publications, customer review directories, and industry trade journals that the AI system trusts when forming its conclusions.
4. Normalization and Sentiment Scoring
Raw text is normalized against standard brand taxonomy rules to prevent corporate parent names from cannibalizing individual product brand visibility. Sentiment analysis models calculate whether the AI narrative portrays the brand positively, neutrally, or negatively regarding customer satisfaction, pricing fairness, and software stability.
Core Metrics Inside a BrandRank.ai Visibility Insights Report
Conducting a brandrank.ai visibility insights analysis requires understanding five fundamental quantitative metrics that define a company’s standing in generative search:
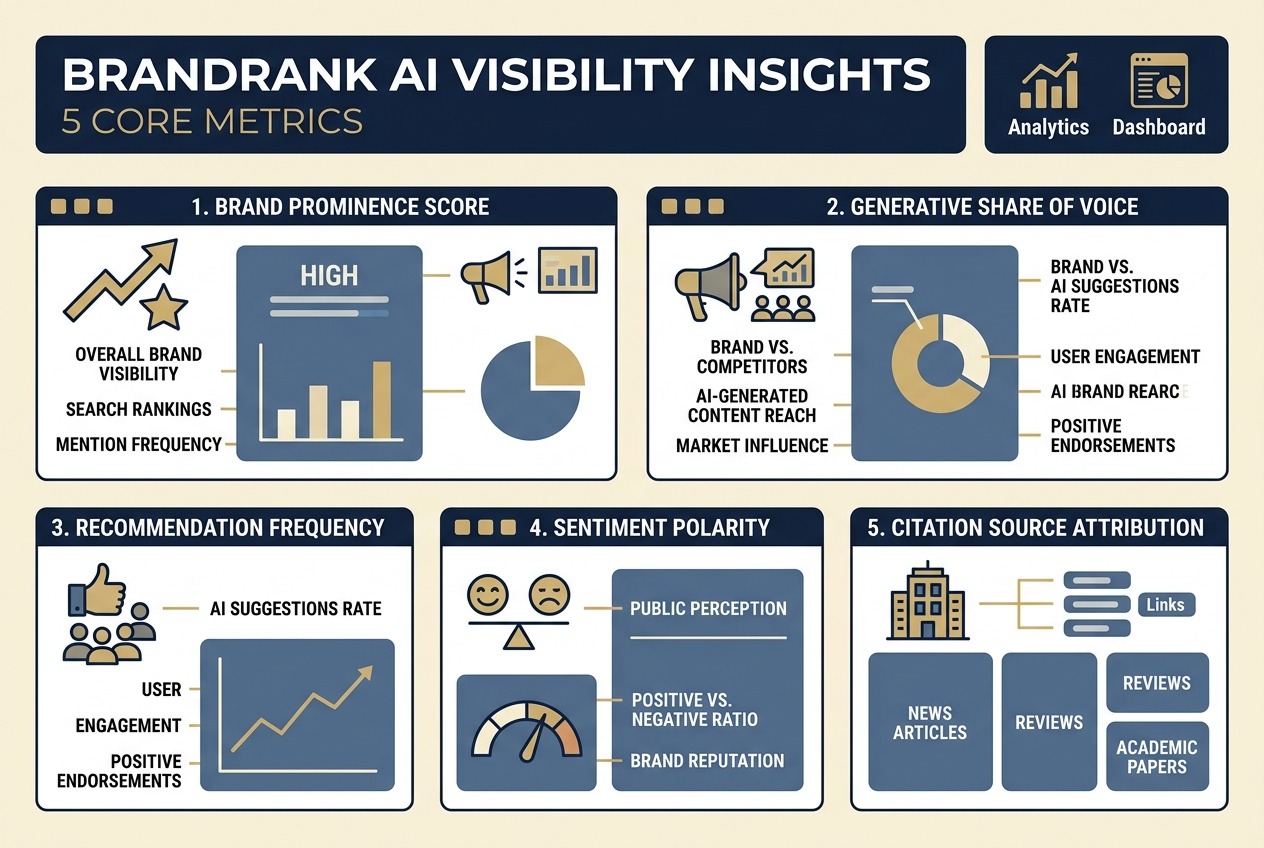
The five core metrics comprising an enterprise BrandRank.ai visibility insights analysis report: prominence score, generative SOV, recommendation rate, sentiment, and citations.
Comparative Matrix: BrandRank.ai vs Traditional Rank Trackers vs RAG Crawlers
To understand where BrandRank.ai fits in the enterprise technology stack, marketing leaders must contrast its capabilities against established organic SEO platforms and raw web scraping tools:
Data analysts evaluate LLM prompt simulations and citation graph sources to optimize brand prominence in answer engines.
Tactical Playbook: How to Act on BrandRank.ai Visibility Insights
Generating a visibility insights report is only the first phase. Marketing organizations must translate diagnostic findings into tactical interventions that systematically improve AI recommendation rates:
1. Fix Entity Salience Across Verified Digital Knowledge Bases
Large language models rely heavily on structured knowledge repositories, including Wikidata, DBpedia, and official government business filings, to confirm entity identity. If an AI model cannot find a clean, disambiguated entity record for your brand, it will assign low confidence to your product offerings. Ensure your company possesses a verified Wikidata entity listing that accurately links your official website, CEO, headquarters, and core product category descriptions.
2. Dominate Third-Party Citation Authority Feeds
When Perplexity, Gemini, or ChatGPT Search generate answers, their RAG algorithms prioritize high-trust independent publications, industry analyst reports (such as Forrester or Gartner), and structured customer review portals (G2, TrustRadius, Capterra). If your visibility insights report indicates that competitors dominate citations, your digital PR program must secure reviews and editorial inclusions in the exact third-party publications that AI algorithms cite as authoritative sources.
3. Deploy Schema.org Structured Data and Entity Disambiguation
Modern AI web search crawlers parse Schema.org JSON-LD microdata directly from web pages. Your technical web team must implement complete Organization, Product, and Service schema on your corporate domain. Explicitly define sameAs arrays linking to your verified social channels, Wikipedia pages, and crunchbase profiles to eliminate entity confusion.
4. Neutralize Negative AI Narrative Hallucinations
If your sentiment polarity index reveals that AI models frequently cite outdated criticism (such as a resolved security bug from 2023 or obsolete legacy pricing), publish dedicated, clear factual documentation addressing those topics directly. Models with real-time web search capabilities index authoritative correction articles, gradually updating their latent weights and synthesized opinions.
Five-Step Enterprise Audit Workflow for Marketing Leaders
To implement continuous generative search governance, corporate marketing teams should execute this five-step operational workflow:
- Establish an Exhaustive Commercial Prompt Corpus: Collaborate with product marketing and sales teams to compile 100 to 300 real-world customer prompts spanning discovery, comparison, pricing, and technical evaluation stages.
- Run an Initial Cross-Engine Visibility Baseline: Execute the prompt corpus across BrandRank.ai to establish your baseline Brand Prominence Score, Generative Share of Voice, and model-by-model recommendation frequency.
- Identify Top Competitor Citation Sources: Export the citation attribution graph to identify which specific digital review portals, media articles, and partner sites competitors rely on for AI recommendations.
- Execute Targeted Content and Digital PR Sprints: Direct your content marketing and external PR teams to earn coverage on high-citation domains and publish technical comparison guides addressing AI content gaps.
- Track Monthly Visibility Velocity: Review BrandRank.ai visibility changes on a monthly basis. Monitor your Brand Prominence Score velocity to verify that optimization efforts translate into increased AI recommendations and higher generative market share.
Frequently Asked Questions
What is the difference between SEO and Generative Engine Optimization (GEO)?
Search Engine Optimization (SEO) focuses on improving keyword rankings on traditional search results pages consisting of links and snippets. Generative Engine Optimization (GEO) focuses on optimizing digital content, entity relationships, and third-party citations so that conversational AI models (such as ChatGPT, Claude, and Perplexity) directly mention and recommend a brand in their synthesized answers.
How often does BrandRank.ai update visibility insights data?
BrandRank.ai executes automated prompt testing continuously, with enterprise dashboards typically updating visibility data on a weekly or daily schedule depending on the tier. Continuous testing accounts for frequent foundational model parameter updates and dynamic web-search index refreshes.
Can small businesses benefit from BrandRank.ai visibility insights?
Yes. While enterprise brands use the platform to protect multi-billion-dollar market shares, small and mid-sized businesses use visibility insights to identify underserved niche prompt queries where legacy competitors have failed to optimize their AI presence, enabling smaller brands to win recommendations in high-intent buyer prompts.
How does BrandRank.ai detect brand hallucinations?
The platform cross-references AI-generated responses against verified corporate data schemas. If an AI engine claims that a software platform lacks a specific feature, quotes incorrect pricing, or invents non-existent integration partners, the platform flags the discrepancy for marketing and legal teams to address.
Which AI search engines have the greatest impact on B2B purchasing decisions?
In 2026, OpenAI ChatGPT and Perplexity drive the highest volume of conversational product evaluations, while Google Gemini and Microsoft Copilot influence users conducting research directly within web browsers and enterprise workplace suites.
Strategic Next Steps for Marketing Executives
Conducting a rigorous brandrank.ai visibility insights analysis is essential for marketing directors determined to lead their industries in the generative search era. As enterprise buyers increasingly replace traditional search queries with AI conversations, brands that monitor, benchmark, and actively optimize their presence inside foundational models will secure decisive competitive advantages that compound across digital channels.
Begin by mapping your commercial product categories against conversational buyer intent prompts, auditing your entity records across digital knowledge graphs, and benchmarking your current Brand Prominence Score against your top three market competitors before allocating your next digital marketing budget cycle.